Datasheets for Datasets: How to Document AI Training Data From Nigeria
Overview & Key Takeaways
Learn why documenting AI training data is crucial for responsible AI development, especially for data from diverse regions like Nigeria. This guide explains the benefits of datasheets and how they improve transparency, accountability, and the effectiveness of AI models.
- Datasheets provide essential metadata about AI training data, including its origin, collection methods, and potential biases.
- Transparent data documentation is vital for building trust and ensuring responsible AI development, aligning with global standards like the EU AI Act.
- Nigerian data, with its linguistic and cultural diversity, requires careful documentation to capture nuances and avoid misrepresentation.
- Datasheets help AI teams understand limitations, mitigate biases, and ensure fair and equitable performance of their models across different user groups.
- Implementing datasheet practices benefits both data creators and data consumers by fostering accountability and improving data quality.
When AI and robotics teams seek high-quality data from Nigeria, they need more than just raw files. They need to understand where the data came from, how it was collected, and what its limitations might be. This is where datasheets for datasets become indispensable. Think of a datasheet like the nutritional label on a food product; it tells you exactly what’s inside, its ingredients, and any potential allergens. For AI training data, this transparency is key to building trustworthy and effective artificial intelligence.
Why Document AI Training Data From Nigeria?
Documenting AI training data from Nigeria is essential for several critical reasons. Nigeria is a hub of linguistic and cultural diversity, with numerous languages, dialects, and unique social contexts. AI models trained on data that doesn't adequately represent this diversity risk performing poorly or exhibiting biases when deployed in real-world Nigerian scenarios. Proper documentation, through datasheets, helps ensure that the data's origin, collection methods, and intended use are clearly understood. This transparency is crucial for building responsible AI, as highlighted by global initiatives like the EU AI Act, Article 10: Data and Data Governance. Furthermore, the National Artificial Intelligence Strategy in Nigeria also emphasizes the importance of ethical data collection and usage.
Without clear documentation, AI models might inadvertently perpetuate stereotypes or fail to recognise nuances in Nigerian languages like Yoruba, Igbo, Hausa, or Nigerian Pidgin. This can lead to models that are not only ineffective but also potentially harmful. By providing comprehensive datasheets, data providers can assure AI developers that the data is suitable for their intended purpose and that ethical guidelines have been followed. This builds confidence and facilitates the responsible development of AI technologies within and for Nigeria.
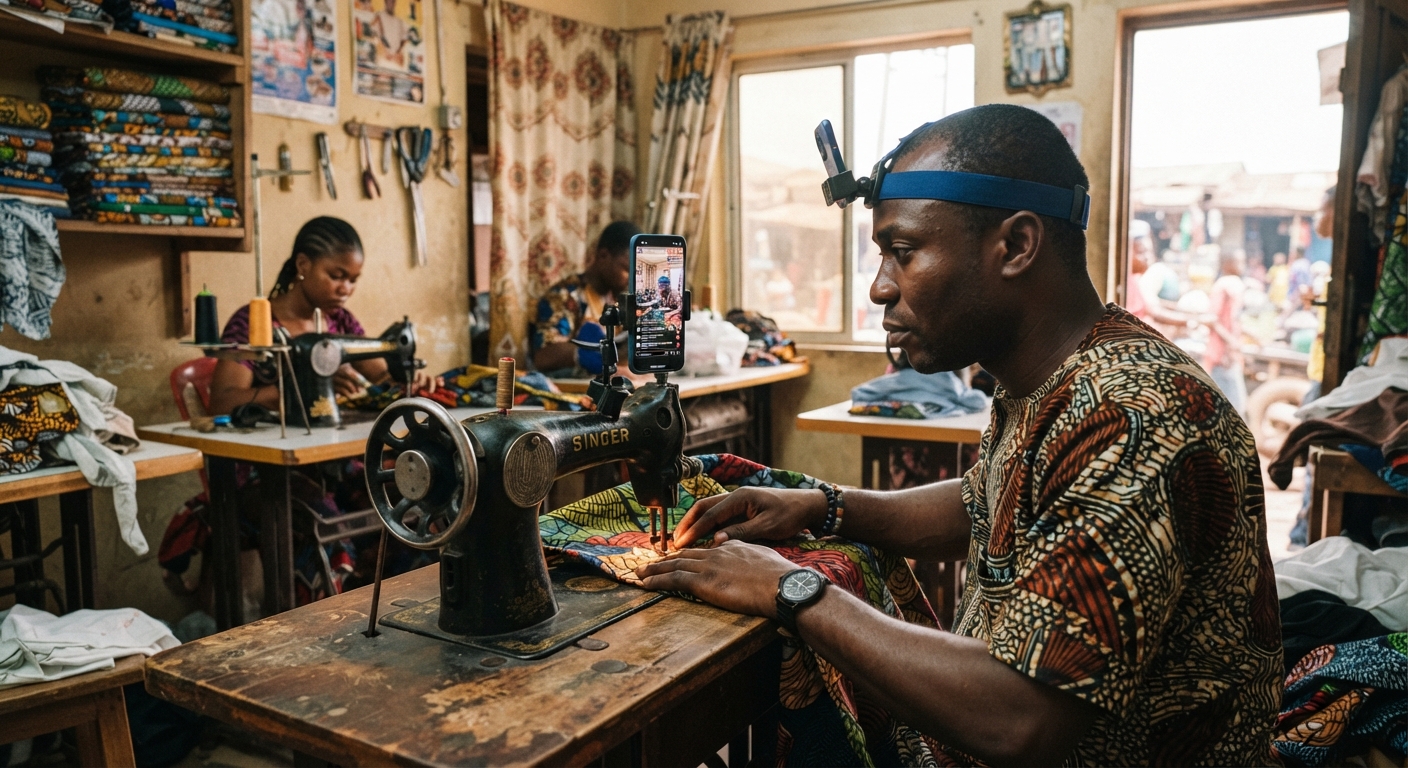
The process of collecting data in Nigeria, as detailed in AI Data Collection in Lagos: What a Recording Pilot Looks Like From the Inside, involves specific steps to ensure authenticity and quality. These steps, when documented in a datasheet, provide invaluable context to buyers. For instance, knowing that recordings were made with contributors who provided explicit consent, as emphasized in How Voice Data Is Collected Ethically: Consent From Every Speaker, is critical for ethical AI development.
What Information Should a Data Datasheet Include?
A comprehensive datasheet for AI training data from Nigeria should cover several key areas, providing a complete picture of the dataset. This includes the dataset's intended use, its creators, and the specific data collection process. Understanding the collection methodology is vital. For example, was the data collected through conversational speech, read speech, or first-person video recordings of work? Each method yields different types of insights and has different implications for AI model performance. For speech data, documenting the languages and dialects present, such as Igbo, Hausa, Yoruba, or Nigerian Pidgin, is crucial, as is noting any code-switching that occurred, which is common in Nigerian conversations.
Here are the essential components of a robust data datasheet:
- Dataset Description: What the dataset is about, its purpose, and the types of data it contains (e.g., video, audio, text).
- Data Collection Process: Details on how the data was gathered, including location (e.g., Lagos, Aba, Kano), time period, recording equipment, and any specific instructions given to contributors. For instance, for speech data, this might include details on spontaneous conversations versus read text, as discussed in Conversational Speech Data vs Read Speech: What AI Teams Need From Nigeria.
- Contributors: Information about the people who provided the data, including demographic details (age, gender, region, language proficiency) where relevant and ethically permissible. For video data, this might include the trade or activity being recorded, such as tailoring, auto mechanics, or cooking.
- Data Features: Specific characteristics of the data, such as resolution and frame rate for video, or audio quality and sampling rate for speech.
- Annotation and Labeling: If the data has been annotated or labeled, details about the process, annotator qualifications, and quality control measures.
- Potential Biases: An honest assessment of any known or potential biases in the data, whether demographic, cultural, or situational. For Nigerian data, this could relate to regional accents or specific cultural practices.
- Limitations and Risks: What the data is NOT suitable for, and potential risks associated with its use.
- Ethical Considerations and Licensing: Information on consent, privacy protection (e.g., blurring of bystander faces), data storage, and the terms under which the data can be used.
The concept of datasheets for datasets was popularized by Google researchers to promote transparency and accountability in machine learning datasets, as outlined in their seminal Datasheets for Datasets paper. Applying this framework to Nigerian data ensures that its unique characteristics are properly understood and leveraged.
Benefits of Using Datasheets for Nigerian AI Data
The adoption of datasheets for AI training data from Nigeria offers significant benefits to both data providers and AI development teams. For AI teams, datasheets provide the necessary context to evaluate the suitability of a dataset for their specific application. This helps them make informed decisions, reducing the risk of using inappropriate data that could lead to poor model performance or unintended consequences. For example, an AI team looking to build a speech recognition system for Nigerian Pidgin would need to know if the data captured various accents and conversational styles, as discussed in Why AI Struggles With Nigerian Pidgin, and How Speech Data Fixes It.
Datasheets also play a crucial role in identifying and mitigating bias. By documenting the demographic makeup and collection context of the data, AI developers can better understand potential disparities and take steps to ensure their models are fair and equitable. This is particularly important in diverse societies like Nigeria, where AI systems must serve a wide range of users. The Nigeria Data Protection Commission (NDPC) also emphasizes the importance of data governance and ethical data handling, which datasheets directly support.
Moreover, datasheets foster accountability. When data collection processes and limitations are clearly documented, it becomes easier to track the provenance of data and hold stakeholders responsible for its quality and ethical use. This transparency builds trust between data providers and consumers, encouraging long-term partnerships. For AI labs looking for reliable data sources, understanding these documentation practices is part of the due diligence, as explored in What to Ask an African Data Vendor Before You Buy AI Training Data. The availability of detailed datasheets also aids in the responsible deployment of AI, ensuring that models perform as expected in the real-world environments they are designed for, whether it's for tasks like auto mechanics or phone repair in places like Computer Village.
Implementing Datasheets in Practice
Implementing datasheets for AI training data from Nigeria requires a structured approach. For data providers like TrustAm, this means integrating datasheet creation into the data collection workflow from the outset. Every step, from contributor verification (using BVN or NIN) and workplace registration by field agents to the in-person consent process and the rigorous minute-by-minute review of recordings, should inform the datasheet. For example, the details of the consent process, including the language used and the date, are crucial pieces of information that would be included.
The process involves:
- Standardised Templates: Developing and using consistent datasheet templates across all data collection efforts. This ensures that all necessary information is captured uniformly.
- Data Provenance Tracking: Maintaining detailed records of where each piece of data originated, who contributed it, and under what conditions it was collected. This includes metadata like GPS coordinates and motion sensor data captured alongside video.
- Bias Auditing: Actively looking for and documenting potential biases in the dataset, whether they stem from the collection methods, the demographics of the contributors, or the specific tasks being recorded.
- Regular Updates: Datasheets are not static documents. They should be updated as new information becomes available or as the dataset is expanded or refined.
- Accessibility: Ensuring that datasheets are easily accessible to the intended users, typically provided alongside the dataset itself.
AI development teams should also make datasheets a mandatory part of their procurement process. When evaluating potential datasets, reviewing the datasheet should be a critical step. This practice aligns with the principles of responsible AI development and ensures that teams are aware of the data's characteristics before they begin training models. This is especially true for specialized data, such as Nigerian-accented English speech data or egocentric video of specific trades, which require detailed contextual information. The AI Training Dataset Market is growing rapidly, and transparency through datasheets will be a key differentiator for high-quality providers.
Frequently Asked Questions
What is the primary purpose of a datasheet for AI training data?
Why is documenting data from Nigeria particularly important?
Who benefits from AI training data datasheets?
How does a datasheet help in mitigating bias in AI models?
What is the role of consent in data documentation?
Can datasheets help in the development of specialized AI models for Nigeria?
Need AI training data from Nigeria?
Egocentric video of skilled work and Nigerian-language speech, collected to order. Email [email protected] or request a free 10-hour sample; a person replies within one working day.
Founder and CEO of TrustAm. Building Nigeria's reputation marketplace for verified service providers. Reviews unlock only after real payments.
Disclosure: This article is published by TrustAm Data, part of TrustAm Limited. Links to /data pages are our own data service.
Sources & References
- EU AI Act, Article 10: Data and Data Governance— artificialintelligenceact.eu
- National Artificial Intelligence Strategy— ncair.nitda.gov.ng
- Datasheets for Datasets— arxiv.org
- Nigeria Data Protection Commission (NDPC)— ndpc.gov.ng
- AI Training Dataset Market— grandviewresearch.com