How to Source Nigerian Language Speech Data for Your AI Model
Overview & Key Takeaways
This article guides AI teams on sourcing authentic Nigerian language speech data, covering the challenges, best practices, and the importance of ethical collection. Learn why diverse Nigerian languages are crucial for building inclusive AI and how TrustAm Data meets these needs.
- Nigeria's linguistic diversity presents both a challenge and an opportunity for AI development.
- Authentic, conversational speech data is vital for accurate AI models.
- Ethical data collection, including informed consent, is paramount.
- TrustAm Data offers a verifiable and secure method for acquiring Nigerian language speech data.
- Understanding nuances like code-switching and regional dialects improves AI performance.
Building artificial intelligence models that understand and interact with people worldwide requires data that reflects global diversity. For AI developers targeting the Nigerian market, this means going beyond English and incorporating the country's rich tapestry of local languages. Sourcing this data effectively is key to creating AI that is truly inclusive and useful. This article explains how AI teams can source Nigerian language speech data, focusing on the practicalities and the importance of quality and ethics.
Why Nigerian Language Speech Data Matters for AI
Nigeria is home to over 500 languages, a linguistic landscape that presents unique opportunities and challenges for AI development. While English is the official language, a vast majority of the population communicates daily in languages such as Hausa, Igbo, Yoruba, and Nigerian Pidgin, along with countless other regional tongues. AI models trained solely on English or limited language sets will inevitably fail to serve a significant portion of the Nigerian population. Developing AI that can understand and respond in these local languages is essential for applications ranging from customer service chatbots and voice assistants to healthcare information systems and educational tools.
Ignoring this linguistic diversity leads to a "data gap," where AI systems perform poorly or are inaccessible to millions. For instance, a voice assistant designed for Nigeria must be able to understand nuances in pronunciation, dialects, and even code-switching, where speakers fluidly move between languages within a single conversation. This is particularly relevant for languages like Nigerian Pidgin, which has its own unique grammar and vocabulary, often mixing elements from English and local languages. As highlighted in Why AI Struggles With Nigerian Pidgin, and How Speech Data Fixes It, specialized data is needed for AI to effectively process these variations.
Furthermore, the development of AI in Nigeria aligns with national strategies. The National Artificial Intelligence Strategy aims to harness AI for socio-economic development, and this includes ensuring AI technologies are accessible across all linguistic groups. Investing in Nigerian language speech data is therefore not just a technical necessity but a strategic imperative for fostering digital inclusion and innovation. The National Artificial Intelligence Strategy emphasizes the need for localized AI solutions, which inherently requires data in local languages.
Challenges in Sourcing Nigerian Language Speech Data
Sourcing high-quality, diverse speech data from Nigeria is not without its hurdles. One primary challenge is the sheer number of languages and dialects, each with its own phonetic characteristics and grammatical structures. Creating comprehensive datasets requires reaching speakers across different regions and ensuring adequate representation for each language. For example, Yoruba can have distinct regional variations, and an AI model needs data that reflects this diversity to perform reliably everywhere. The article Yoruba Speech Data for AI: Tones, Dialects and What Makes a Good Recording details these specific challenges for Yoruba.
Another significant obstacle is the availability of authentic conversational speech. Much of the speech data used in AI development historically comes from read speech, where individuals read pre-written text aloud. While useful for some tasks, it doesn't capture the natural flow, hesitations, background noise, and code-switching common in everyday Nigerian conversations. This is why Conversational Speech Data vs Read Speech: What AI Teams Need From Nigeria stresses the importance of unscripted audio.
Moreover, technical limitations can hinder data collection. Many potential contributors may lack access to high-quality recording equipment or stable internet connections needed to upload large audio files. Ensuring consistent audio quality across different recording environments and devices is crucial for training robust AI models. Factors like background noise, microphone quality, and speaker distance can all impact the usability of the data.
Best Practices for Ethical Data Collection
Ethical considerations are paramount when collecting any form of personal data, especially voice recordings. For AI teams sourcing data from Nigeria, adhering to data protection regulations and ethical guidelines is non-negotiable. This includes obtaining informed consent from every individual whose voice is recorded. Consent should be explicit, clearly stating how the data will be used, who will have access to it, and for how long it will be stored. As detailed in How Voice Data Is Collected Ethically: Consent From Every Speaker, this is a fundamental requirement.
Transparency is key. Contributors must understand that their recordings will be used to train AI models. They should also be aware of their rights, including the right to withdraw consent and request data deletion at any time. This aligns with global data protection standards, such as those outlined by the Nigeria Data Protection Commission (NDPC) and directives like the NDP Act General Application and Implementation Directive (GAID) 2025. Respecting these rights builds trust and ensures sustainable data collection practices.
Anonymization and privacy protection are also critical. While voice data itself can be identifying, steps must be taken to protect contributor privacy. This includes blurring faces in any accompanying video, anonymizing speaker identities where possible, and securely storing personal information. For AI training data, it's often the speech itself, not the identity of the speaker, that is valuable. Buyers of data also have responsibilities, as detailed in the Nigerian AI Training Data Buyers Guide, including understanding the provenance and ethical sourcing of the data they acquire.
TrustAm Data: A Solution for Nigerian Language Speech Data
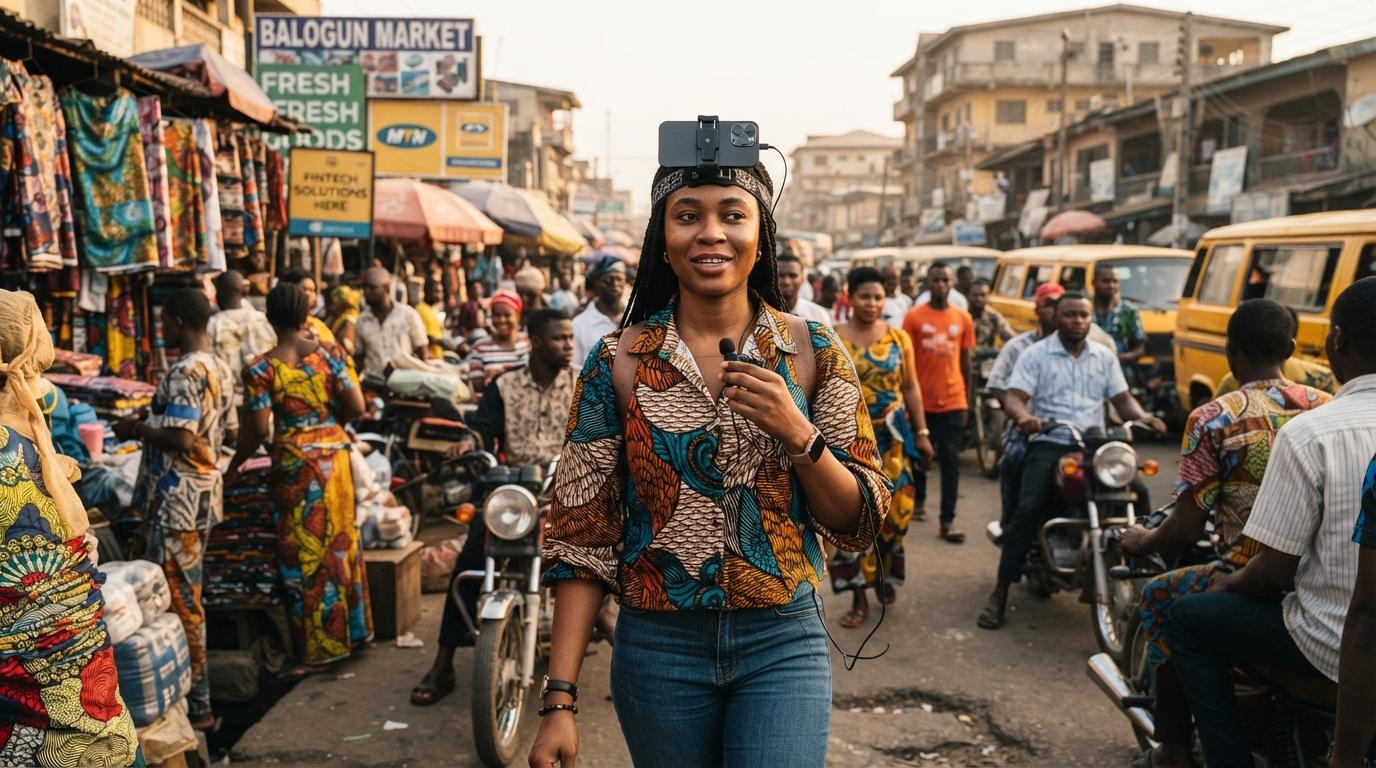
TrustAm Data offers a robust and ethical solution for AI teams looking to source Nigerian language speech data. Operating a pilot in Lagos, TrustAm focuses on collecting first-person work videos and Nigerian-language speech from individuals across various trades. This approach ensures the data is not only linguistically diverse but also contextually rich, capturing real-world usage.
TrustAm's rigorous verification process for contributors builds trust and ensures data integrity. Contributors undergo BVN or NIN checks, live selfie verification, and payments are made only to bank accounts matching their verified identity. This one-person, one-account policy prevents fraud and ensures accountability. All recording locations are physically registered and consented to by the owner before any data collection begins, providing a secure and legitimate environment for recording.
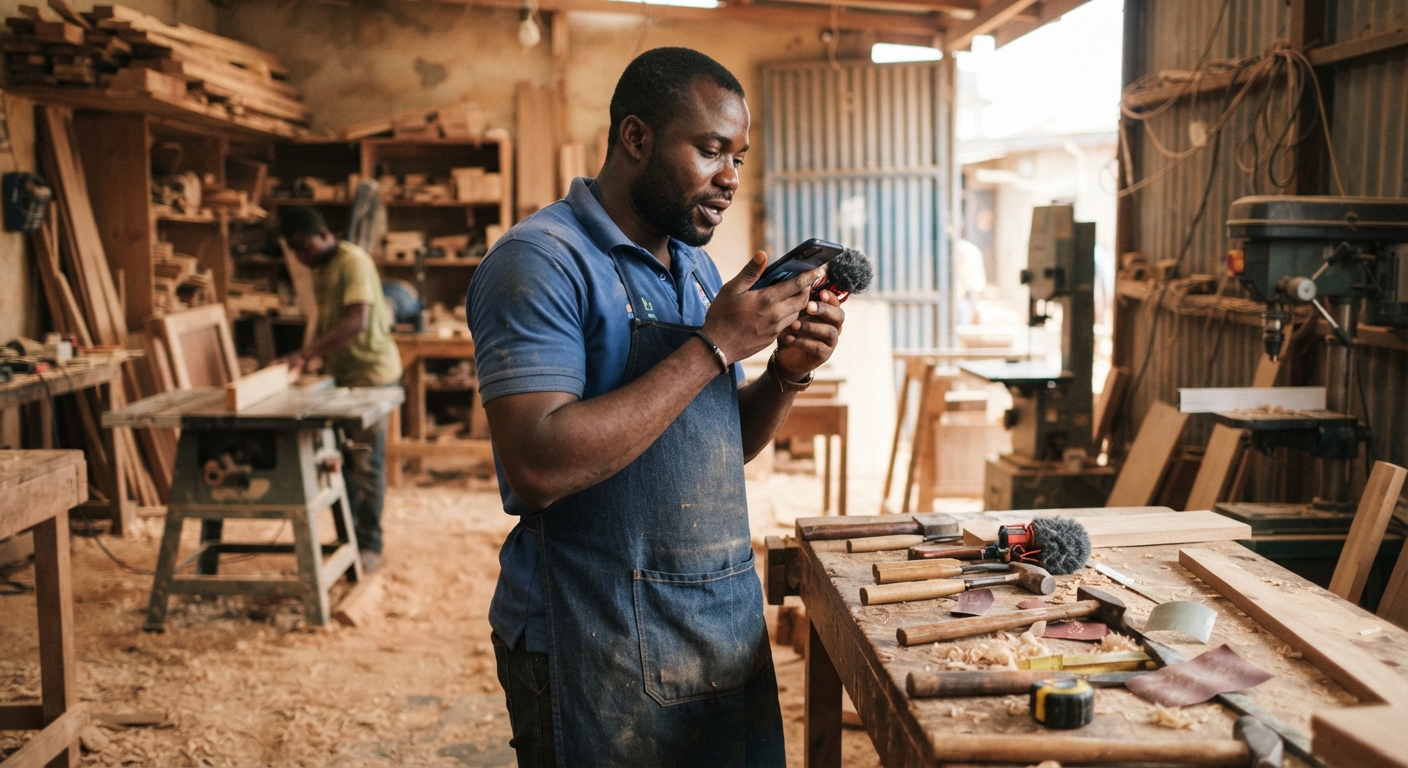
The quality control process at TrustAm is extensive. Each recording is reviewed minute by minute by trained personnel. Automatic checks for technical issues like black frames or frozen video are performed, followed by human review. Contributors are paid only for approved minutes, and detailed feedback is provided for any rejected segments, encouraging continuous improvement. This meticulous approach guarantees that the data supplied to AI teams is of high quality and adheres to the specified requirements.
TrustAm Data supports a wide range of Nigerian languages and dialects, including English, Nigerian Pidgin, Yoruba, Igbo, and Hausa. This breadth of coverage allows AI developers to build models that cater to a diverse user base. Whether you need conversational data for chatbots, specific dialects for voice recognition systems, or even data that captures code-switching patterns, TrustAm can facilitate your needs. For AI labs seeking to expand their reach, TrustAm provides access to datasets that are otherwise difficult to obtain, supporting the development of AI that truly understands Nigeria. Explore the possibilities with TrustAm Data: real-world data from Nigeria.
Languages and Dialects Covered
TrustAm Data's current pilot in Lagos is actively collecting speech data in several key Nigerian languages. This includes:
- English: Standard and Nigerian-accented English, crucial for many cross-functional applications.
- Nigerian Pidgin: A widely spoken lingua franca, essential for any AI targeting broad communication.
- Yoruba: With various dialects spoken across the Southwest and beyond.
- Igbo: Spoken by millions in the Southeast and diaspora.
- Hausa: A major language in Northern Nigeria and parts of West Africa.
The project is continually expanding its scope, aiming to capture more regional variations and less commonly documented languages as demand grows. This commitment to linguistic diversity ensures that AI models can be developed for a truly representative slice of the Nigerian population. For teams focusing on specific language needs, TrustAm offers custom data collection services to meet precise specifications. More information on available datasets can be found at the dataset library.
The inclusion of these languages is vital for several reasons. Firstly, it enables the development of more accurate speech recognition systems. AI models trained on diverse linguistic inputs are better equipped to handle variations in pronunciation, tone, and accent, reducing errors and improving user experience. As discussed in Nigerian-Accented English and Speech Recognition: Why Accents Need Their Own Data, accent-specific data is a game-changer.
Secondly, it facilitates the creation of natural language understanding (NLU) and natural language generation (NLG) models that can process and generate text or speech in local languages. This is critical for applications like local language search engines, translation services, and content creation platforms. The Masakhane initiative, for example, highlights the growing need for African language NLP resources, a need TrustAm aims to help fill.
Finally, it addresses the digital divide by making technology accessible to those who are not fluent in English. By supporting local languages, AI can empower communities, improve access to information, and foster greater digital inclusion across Nigeria. The Lacuna Fund supports projects that aim to close data gaps for under-represented languages, a mission that aligns with TrustAm's goals.
What Buyers Can Expect
AI and robotics teams looking to purchase data from TrustAm Data can expect a structured and transparent process. TrustAm provides a free 10-hour sample, recorded to the buyer's specific requirements, allowing teams to evaluate the data quality and relevance before committing to a larger purchase. This initial sample is crucial for scoping the project and ensuring alignment with the AI model's needs.
Following the sample, buyers can opt for a paid pilot project ranging from 100 to 500 hours. Weekly batches are delivered with comprehensive Quality Assurance (QA) reports, detailing the data's characteristics and any findings. This iterative approach allows for feedback and adjustments throughout the data collection process. The eventual goal is a monthly contract for ongoing data supply, ensuring a continuous stream of relevant training data.
The data is delivered in blurred MP4 format (1080p30) along with per-clip JSON metadata. This metadata includes crucial information for training AI models, such as timestamps, transcribed text, and labels. Manifests with consent IDs and QA reports are also provided, ensuring full traceability and compliance. For advanced users, LeRobot and RLDS formats are available upon request, facilitating integration with popular AI frameworks. TrustAm's commitment to quality and ethical sourcing makes it a reliable partner for developing AI solutions for the Nigerian market. For more details on acquiring data, visit data for AI and robotics labs.
Frequently Asked Questions
Is sourcing speech data from Nigeria legal?
What types of Nigerian languages can I get data for?
How does TrustAm ensure the quality of speech recordings?
What are the privacy protections for data contributors?
Can I get a sample of the data before purchasing?
Need AI training data from Nigeria?
Egocentric video of skilled work and Nigerian-language speech, collected to order. Email [email protected] or request a free 10-hour sample; a person replies within one working day.
Founder and CEO of TrustAm. Building Nigeria's reputation marketplace for verified service providers. Reviews unlock only after real payments.
Disclosure: This article is published by TrustAm Data, part of TrustAm Limited. Links to /data pages are our own data service.
Sources & References
- National Artificial Intelligence Strategy— ncair.nitda.gov.ng
- NDP Act General Application and Implementation Directive (GAID) 2025— ndpc.gov.ng
- Masakhane— masakhane.io
- Lacuna Fund— lacunafund.org
- National Information Technology Development Agency (NITDA)— nitda.gov.ng
- Ego4D: Around the World in 3,000 Hours of Egocentric Video— arxiv.org
- EPIC-KITCHENS— epic-kitchens.github.io
- LeRobot— github.com