Igbo Language AI in 2026: The Data Gap and How to Close It
By 2026, artificial intelligence systems are expected to understand and generate Igbo, Nigeria's third most spoken language. But for this to happen, AI companies need a lot more Igbo language data. Right now, there is a significant gap in the amount and quality of Igbo speech and text available for training these AI models. This article looks at why this data gap exists and how it can be filled.
Overview & Key Takeaways
This article explores the current shortage of Igbo language data for AI development and outlines practical solutions. It covers the importance of local data, the challenges in collection, and how Nigerian contributors can help bridge this gap to improve AI services for Igbo speakers.
- AI development for Igbo language requires a substantial increase in high-quality speech and text data.
- Current data limitations hinder the effectiveness of AI tools for Igbo speakers in Nigeria.
- Collecting diverse Igbo speech data is crucial for training accurate voice assistants and translation models.
- Nigerian contributors can earn by providing approved recordings of their everyday work and conversations.
- TrustAm Data offers a safe and verified platform for individuals to contribute their Igbo language data.
Why Does AI Need So Much Igbo Language Data?
AI models, especially those dealing with natural language processing (NLP) and speech recognition, learn by example. The more examples they have, the better they become at understanding nuances, accents, and context. For Igbo, this means AI needs thousands of hours of spoken Igbo from diverse speakers across different regions and in various contexts. Without this data, AI systems can struggle to understand Igbo speakers accurately, leading to poor performance in applications like voice assistants, translation tools, and chatbots.
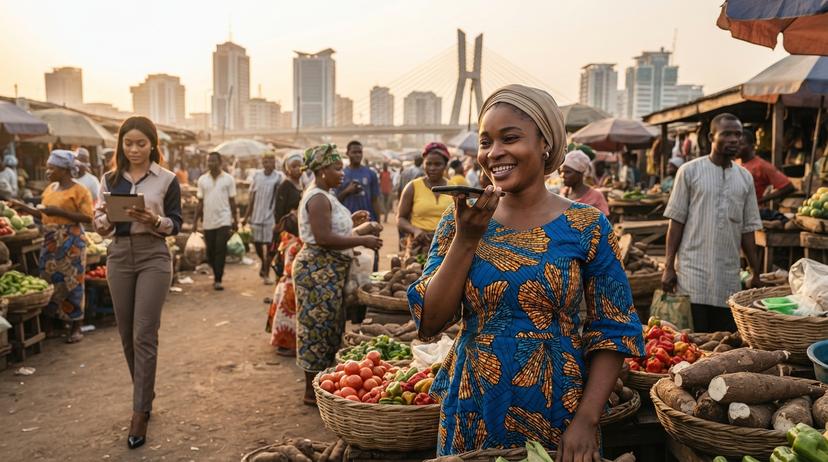
The lack of sufficient data is a common problem for many African languages. While languages like English have vast datasets, many local languages are underrepresented. This leads to a digital divide where AI-powered services are less effective or unavailable for millions of speakers. Improving AI for Igbo means building models that can understand the full spectrum of the language, from standard Igbo to regional dialects and everyday slang used by market traders in Onitsha or phone repairers in Computer Village.

The Igbo Data Gap: Challenges in Collection
Collecting Igbo language data presents several unique challenges. Firstly, Igbo is spoken by millions across Nigeria and the diaspora, with significant regional variations in pronunciation, vocabulary, and grammar. A dataset needs to reflect this diversity to be truly useful. Secondly, much of the Igbo language is spoken, not written, making it harder to gather large text datasets. Spoken data collection requires careful planning and execution to ensure quality and accuracy.
Another hurdle is the digital infrastructure. While many Nigerians own smartphones, consistent internet access and data bundles can be expensive, making it difficult for potential contributors to upload large audio or video files. Furthermore, awareness about the value of language data for AI development is still low. Many people may not realise that their everyday conversations or work-related instructions in Igbo are valuable assets for cutting-edge technology. TrustAm is working to bridge this gap by making the process of contributing data safe, accessible, and rewarding for Nigerians.
Closing the Gap: How Nigerians Can Contribute Igbo Data
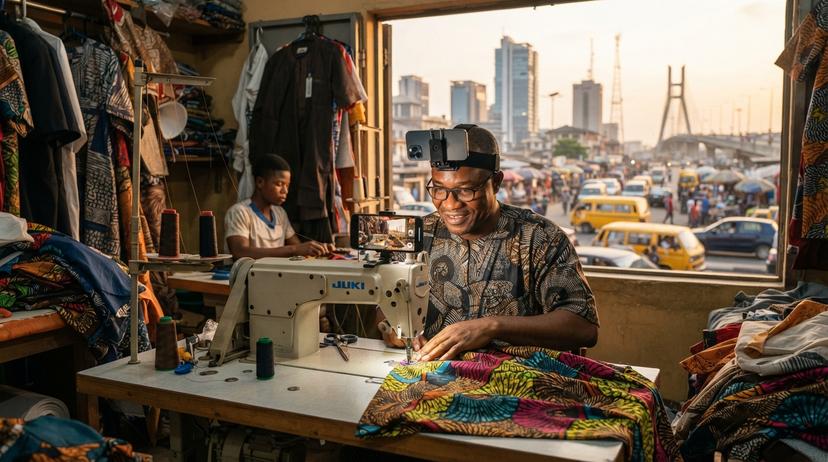
Filling the Igbo data gap requires active participation from native speakers. AI companies and data providers like TrustAm are looking for individuals willing to record their voices and everyday activities. This can include anything from casual conversations with friends and family, to work-related tasks. For example, a tailor in Aba might record instructions on how to cut fabric using Igbo terms, or a phone repair technician might explain a diagnostic process in Igbo. These real-world recordings are invaluable.
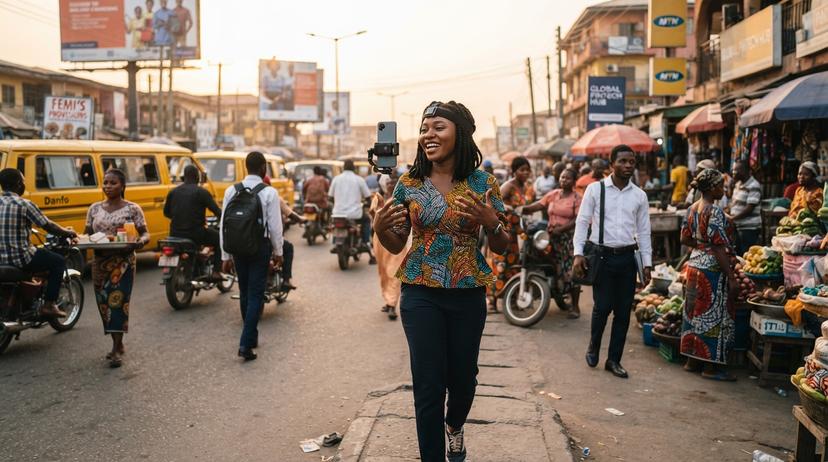
TrustAm makes it simple for individuals to contribute. By using a smartphone app, approved recorders can capture audio and video of their work or conversations. The process is designed to be secure and transparent, with rigorous checks to ensure data quality and contributor verification. As outlined in the Lagos pilot, every recording is reviewed, and contributors are paid for approved minutes. This ensures that the data collected is not only diverse but also meets the high standards required by AI developers.

The Role of TrustAm in Igbo Language AI Development
TrustAm is committed to building high-quality AI datasets from Nigeria, including for indigenous languages like Igbo. The company focuses on ethical data collection, ensuring that all contributors are properly identified, their workplaces are verified, and they give informed consent before any recording begins. This approach aligns with Nigeria's data protection regulations, such as those guided by the Nigeria Data Protection Commission (NDPC).
For Igbo language AI, TrustAm's platform allows for the collection of diverse speech data. Contributors can record themselves speaking Igbo in various contexts, from simple greetings to complex technical discussions. This helps create more robust and accurate AI models. The company also supports video recordings of work activities, which can be invaluable for training embodied AI systems that need to understand human actions and instructions given in Igbo. This is part of a broader effort to ensure that AI development is inclusive and benefits all language communities in Nigeria, as supported by initiatives like the National Centre for Artificial Intelligence and Robotics (NCAIR).
What AI Buyers Need and How TrustAm Delivers
AI and robotics teams are constantly seeking high-quality, diverse, and ethically sourced data. For Igbo language AI, buyers need datasets that capture the natural speech patterns, accents, and dialects of the language. They require recordings that are clear, well-annotated, and come with verified consent. TrustAm provides exactly this. We offer free 10-hour sample datasets tailored to specific requirements, allowing AI developers to test the quality and relevance of our data.
Our data is collected under strict quality control measures. Each recording is reviewed by trained personnel, and metadata such as consent IDs and regional dialect information is provided. This ensures that buyers receive reliable data for their AI projects. Whether it's speech data for a new voice assistant or video data for a robotic system learning Igbo commands, TrustAm can deliver. For AI labs looking to develop Igbo language capabilities, TrustAm offers a direct path to acquiring the necessary data through our verified collection processes. Learn more about our offerings at TrustAm Data: real-world data from Nigeria.
Frequently Asked Questions
Is recording my Igbo conversations for AI safe?
How much can I earn from recording my Igbo speech?
What kind of Igbo speech data is most needed?
Do I need a special phone to record Igbo data?
What happens to recordings that are not approved?
Where can I learn more about AI data collection in Nigeria?
Need AI training data from Nigeria?
Egocentric video of skilled work and Nigerian-language speech, collected to order. Email [email protected] or request a free 10-hour sample; a person replies within one working day.
Founder and CEO of TrustAm. Building Nigeria's reputation marketplace for verified service providers. Reviews unlock only after real payments.
Disclosure: This article is published by TrustAm Data, part of TrustAm Limited. Links to /data pages are our own data service.
Sources & References
- Nigeria Data Protection Commission (NDPC)— ndpc.gov.ng
- National Centre for Artificial Intelligence and Robotics (NCAIR)— ncair.nitda.gov.ng
- AfriSpeech-200: Pan-African Accented Speech Dataset (arXiv)— arxiv.org