Read-aloud prompts, five Nigerian languages
Short scripted clips read by native speakers in English, Pidgin, Yorùbá, Igbo and Hausa.
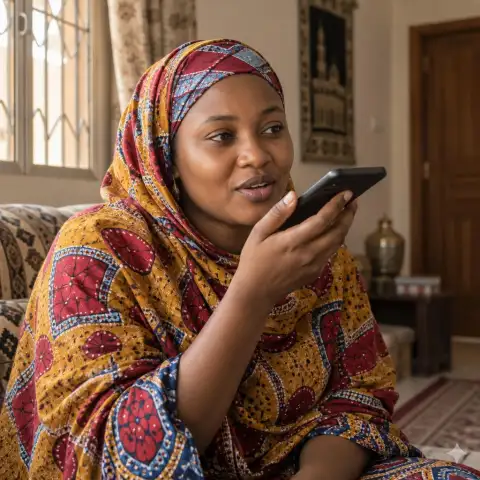
Samples are blurred and watermarked, 30 to 60 seconds. Request the full 10-hour sample on the right.
Prompted read speech, up to about 20 seconds per clip, from ID-checked native speakers across Nigerian accents. Prompt lists to the buyer's spec.
- WAV 48 kHz / 16-bit
- JSON metadata per clip
- Transcripts (JSON, time-aligned) when labelled
Trimmed to approved minutes only, with a review score on every clip.
21 keypoints per hand per frame, with a confidence score.
Start and end times for each step of the task, in plain verbs.
A short description of what is happening, every few seconds.
Verbatim transcript per speaker, in the language spoken.
| Field | Type | What it holds |
|---|---|---|
| clip_id | string | Stable clip ID |
| duration_s | number | Clip length in seconds |
| trade | string | Trade slug |
| contributor_id | string | Pseudonymous contributor ID |
| consent_id | string | Consent record ID |
| consent_version | string | Consent text version |
| capture_date | date | Capture date (WAT) |
| device_model | string | Phone model |
| qa_score | number | 0–1 review score |
| language | string | Language code (en, pcm, yo, ig, ha) |
| speakers | number | Number of consented speakers |
Non-exclusive licence for AI training. Every contributor is ID-checked and consented on video in their own language; bystander faces are blurred; every minute is reviewed by a person.
Related datasets
All datasets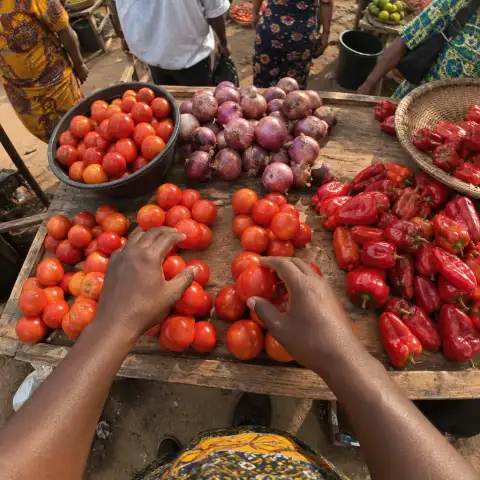
Market conversation, Nigerian Pidgin
Natural two-speaker conversations between traders and regular customers, recorded on clip-on mics.
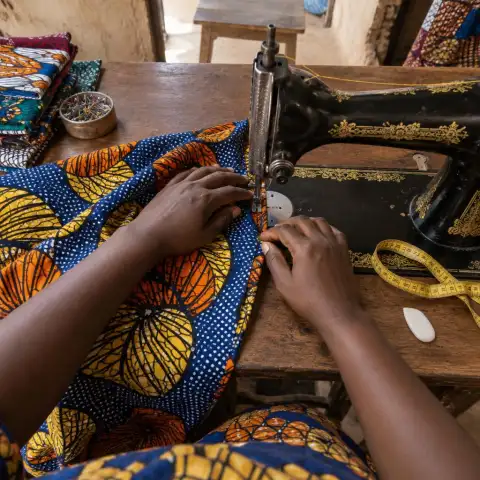
Tailoring, first-person
Head-mounted video of Lagos tailors measuring, cutting and sewing in their own shops.
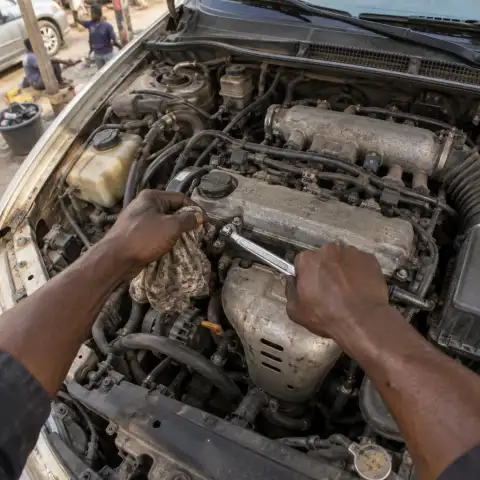
Auto mechanic, first-person
Mechanics diagnosing and repairing cars and motorcycles in roadside and workshop settings.