Human demonstration video for robot manipulation and VLA models.
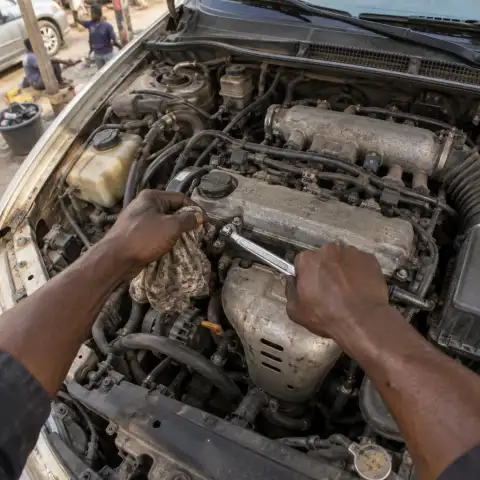
Vision-language-action models learn from many hours of people doing real tasks. We record skilled Nigerian workers, hands in view, with sensors and language captions, and deliver it in the formats robot-learning teams use.
Free 10-hour sample first. A person replies within one working day.
Where the data runs short.
Teleoperation does not scale cheaply
Robot teleop data is slow to collect. Many teams pre-train on large amounts of human video, then fine-tune on a smaller set of robot data.
Same rooms, same tasks
Public datasets repeat Western kitchens and labs. Policies need the variety of real workshops, markets and kitchens.
Language grounding
VLA models need actions tied to words: what is being done, with what, and why. Captions and action segments supply that.
What you get from TrustAm Data.
- Footage
- Head-mounted first-person video, 1080p30, long uncut task sequences
- Sensors
- IMU and GPS sidecars; buyer stereo, depth or multi-camera rigs fitted on request
- Labels
- 21-keypoint hand pose, action segments with verbs and objects, free-text captions
- Formats
- MP4 + JSON, LeRobot or RLDS on request
- Not offered
- Robot teleoperation; we record human demonstrations only
Scope it so the first sample is useful.
- List the tasks and objects your robot must handle; we map them to trades
- Say if you need both hands in view most of the time (we cut minutes that miss it)
- Choose label layers: curated only, or hand pose, action segments and captions
- Pick a format (raw MP4 + JSON, LeRobot, RLDS) and a weekly batch size
Provenance on every minute.
ID-checked recorders
BVN or NIN plus a live selfie matched to the ID, and a bank account in the same name, before any paid task.
Consenting workplaces
Each workplace is registered in person by a TrustAm field agent, with the owner’s consent and a location fence.
Live capture only
A spoken challenge code, motion sensors and GPS show each clip was filmed live, at work. No camera-roll uploads.
Blurred and reviewed
Bystander faces and number plates are blurred; a trained reviewer approves or cuts every minute before delivery.
Buyers usually ask.
Do you offer robot teleoperation data?
No. We record human demonstrations: first-person video of people doing real work, with sensors and labels. Many teams pair this with a smaller teleop set of their own.
Can captions be in English?
Yes. Captions and action labels are in English by default. Workers’ speech in the background can be transcribed too.
Can you deliver in LeRobot or RLDS format?
Yes, on request. We agree the schema with you during the free sample so the pilot drops straight into your pipeline.
How do I start?
Email [email protected] or use the request form. A person replies within one working day and we record a free sample of about 10 hours to your spec. Pricing is quoted per approved hour after scoping.
More from TrustAm Data.
Tell us what you need. We send a free sample first.
Email [email protected] with the data type, hours, languages or trades, labels and format. Pricing is quoted per approved hour after scoping.