Hausa speech data for ASR and TTS, from consenting speakers.
Read and conversational Hausa from ID-checked speakers who consent on record, transcribed in standard Latin (Boko) spelling with the hooked letters, and region recorded for every clip.
Free 10-hour sample first. A person replies within one working day.
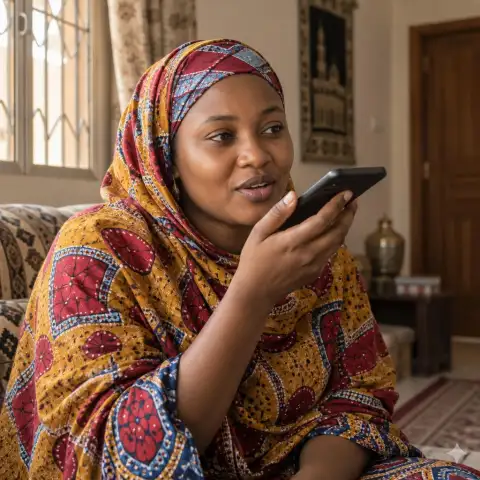
Hausa at a glance.
Spoken across northern Nigeria (Kano, Kaduna, Katsina, Sokoto and beyond) and in Niger, Ghana and other West African countries, as a first language and as a widely used trade language.
- Code
- ha (ISO 639-1)
- Script
- Latin (Boko) with hooked letters ɓ, ɗ, ƙ and ʼy; Arabic-based Ajami exists and can be discussed
- Tone and length
- Hausa marks tone and vowel length in teaching texts but rarely in everyday writing; we add them on request
- Dialects
- Standard (Kano-based) Hausa by default; other regional varieties tagged when you need them
What speech models get wrong.
Hooked letters
ɓ, ɗ and ƙ are often typed as b, d and k online, so clean transcripts with the right letters are scarce.
Tone and vowel length
Both carry meaning but are rarely written, which makes text-to-speech and pronunciation hard.
Arabic and English loanwords
Everyday Hausa borrows from Arabic and English; transcription guides must handle both.
Read prompts or conversation? Usually both.
For speech recognition (ASR)
For ASR we record many speakers on read prompts and conversation, transcribed with the hooked letters so your text normaliser has clean targets.
For text-to-speech (TTS)
For TTS we record a few speakers for longer from a balanced prompt list, with tone and length marked on request, and voice-synthesis consent named explicitly.
A fair mix of real speakers.
- Speakers by region of origin, age band and gender to a quota you set
- Lagos-based Hausa speakers first; northern cities such as Kano are on our next list
- Every speaker ID-checked so one voice is one person
- Market, transport, farming, family and service topics
How each clip is recorded and delivered.
- Audio
- WAV 48 kHz, 16-bit, mono per speaker (one track each in two-person sessions)
- Tasks
- Read prompts (your list or ours), natural two-person conversation, scripted service dialogues
- Transcripts
- UTF-8, one per clip, speaker turns and non-speech events marked; second-pass checks on every batch
- Metadata
- Language, age band, gender, region, device, consent ID and consent version per clip
- Consent
- Recorded in the speaker’s own language; voice synthesis (TTS) named explicitly when it applies
- Delivery
- Weekly batches over signed links, with a manifest and a QA report
Honest advice: what to try before buying.
NaijaVoices (open, non-commercial)
NaijaVoices is an open speech dataset of Igbo, Hausa and Yorùbá released under CC BY-NC-SA 4.0, which does not allow commercial use. Good for research and benchmarks; licensed data is for products.
Open sets exist; check their licences
Hausa appears in open collections such as Mozilla Common Voice and academic corpora. Use them to start; we supply licensed, consented data to your spec.
Source: Mozilla Common Voice
Buyers usually ask.
Can you transcribe in Ajami (Arabic script)?
Our default is Latin (Boko) spelling with hooked letters. Ajami transcription can be scoped per order if you need it.
Are speakers recorded in northern Nigeria?
Today our speakers are in Lagos, which has a large Hausa-speaking community. Kano is on our list of next cities, opened when buyer orders need it.
How do I order Hausa speech data?
Email [email protected] or use the request form with the hours, read/conversation split, speaker mix and transcript rules you need. We record a free sample of about 10 hours to your spec first. Pricing is quoted per approved hour after scoping.
How do speakers consent?
Each speaker passes an ID check and records consent in their own language before any paid task. If the data will be used for voice synthesis (TTS), that use is named explicitly. Speakers can withdraw from future deliveries.
More from TrustAm Data.
- Nigerian Pidgin speech dataLanguage code pcm
- Yorùbá speech dataLanguage code yo
- Igbo speech dataLanguage code ig
- Nigerian-accented English speech dataLanguage code en
- ASR for African languagesUse case
- TTS voicesUse case
- Nigerian speech dataFive languages, one order
- African language dataLow-resource languages, consented
- Matching datasetsCollect-to-order listings
Tell us what you need. We send a free sample first.
Email [email protected] with the data type, hours, languages or trades, labels and format. Pricing is quoted per approved hour after scoping.