Nigerian-accented English speech data for accent-robust voice AI.
English as Nigerians speak it, with accents shaped by Yorùbá, Igbo, Hausa, Pidgin and other first languages. Read prompts and natural conversation from ID-checked, consenting speakers, with first language recorded for every clip.
Free 10-hour sample first. A person replies within one working day.
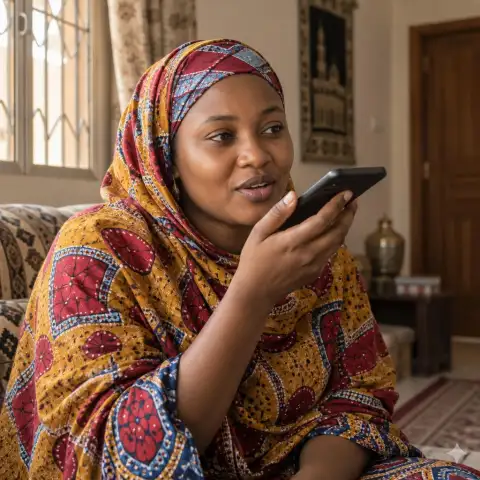
Nigerian-accented English at a glance.
English is Nigeria’s official language, used in schools, government, business and media, and spoken with accents that follow each speaker’s first language and region.
- Code
- en (tagged en-NG in metadata)
- Spelling
- Standard English spelling; Nigerian English words and expressions kept as spoken
- Code-switching
- Switches into Pidgin, Yorùbá, Igbo or Hausa transcribed and tagged per word on request
- Metadata
- First language, region, age band, gender, education band (optional), device
What speech models get wrong.
Accent gaps in big models
Speech models trained mostly on US and UK English make more errors on African accents, a gap research groups have documented.
Nigerian vocabulary
Words and expressions such as “flash me”, “go-slow” and local names need to be in the training text, not treated as errors.
Mixed-language turns
Real conversations slide between English and Pidgin or a local language, often within one sentence.
Read prompts or conversation? Usually both.
For speech recognition (ASR)
For accent-robust ASR we record a broad mix of first languages and regions on read prompts and conversation, with first language in the metadata so you can measure error rates per accent.
For text-to-speech (TTS)
For a Nigerian English TTS voice we record a few speakers for longer in quiet rooms, with voice-synthesis consent named explicitly.
A fair mix of real speakers.
- Speakers balanced by first language (Yorùbá, Igbo, Hausa, Pidgin, others) to your quota
- Age band and gender balance agreed up front
- Every speaker ID-checked so one voice is one person
- Service, customer-support, banking, health and everyday topics
How each clip is recorded and delivered.
- Audio
- WAV 48 kHz, 16-bit, mono per speaker (one track each in two-person sessions)
- Tasks
- Read prompts (your list or ours), natural two-person conversation, scripted service dialogues
- Transcripts
- UTF-8, one per clip, speaker turns and non-speech events marked; second-pass checks on every batch
- Metadata
- Language, age band, gender, region, device, consent ID and consent version per clip
- Consent
- Recorded in the speaker’s own language; voice synthesis (TTS) named explicitly when it applies
- Delivery
- Weekly batches over signed links, with a manifest and a QA report
Honest advice: what to try before buying.
Start with open benchmarks
AfriSpeech-200 from Intron Health is an open accented-English dataset that includes Nigerian accents, useful for benchmarking. We supply licensed, consented data to your spec when you need more.
Source: AfriSpeech-200 on Hugging Face
Buyers usually ask.
Can I measure my model’s error rate by accent?
Yes. Every clip carries the speaker’s first language and region, so you can split your test set by accent group and compare.
Do you record domain-specific English, like banking or health?
Yes. Send us your prompt list or topics and we brief speakers; conversation tasks can be set in a domain too.
How do I order Nigerian-accented English speech data?
Email [email protected] or use the request form with the hours, read/conversation split, speaker mix and transcript rules you need. We record a free sample of about 10 hours to your spec first. Pricing is quoted per approved hour after scoping.
How do speakers consent?
Each speaker passes an ID check and records consent in their own language before any paid task. If the data will be used for voice synthesis (TTS), that use is named explicitly. Speakers can withdraw from future deliveries.
More from TrustAm Data.
- Nigerian Pidgin speech dataLanguage code pcm
- Yorùbá speech dataLanguage code yo
- Igbo speech dataLanguage code ig
- Hausa speech dataLanguage code ha
- ASR for African languagesUse case
- TTS voicesUse case
- Nigerian speech dataFive languages, one order
- African language dataLow-resource languages, consented
- Matching datasetsCollect-to-order listings
Tell us what you need. We send a free sample first.
Email [email protected] with the data type, hours, languages or trades, labels and format. Pricing is quoted per approved hour after scoping.