Hand Pose and Action Labels: How First-Person Work Video Gets Annotated
AI and robotics teams need to understand human actions to build smarter systems. First-person, or egocentric, video is key because it shows the world from a human's perspective. But raw video is just pixels. To make this data useful, it needs to be annotated with labels that describe what's happening. This means identifying hand poses, object interactions, and the overall actions being performed. TrustAm's data annotation process turns raw footage of Nigerian workers into structured, AI-ready datasets.
Overview & Key Takeaways
This article explains how first-person work video, particularly from Nigerian professionals, is annotated for AI training. It details the process of labeling hand poses and actions, the tools used, and why accurate annotation is vital for developing intelligent machines. We cover the importance of context, the role of human reviewers, and the benefits for AI development.
- Accurate annotation of first-person video is crucial for AI and robotics development.
- Hand pose estimation and action labeling provide detailed insights into human behaviour.
- TrustAm employs trained reviewers to ensure high-quality annotations from Nigerian work environments.
- Contextual understanding is essential for correctly labeling complex actions.
- Annotated data powers advancements in fields like robotics, human-computer interaction, and AI safety.
Why Annotate First-Person Work Video?
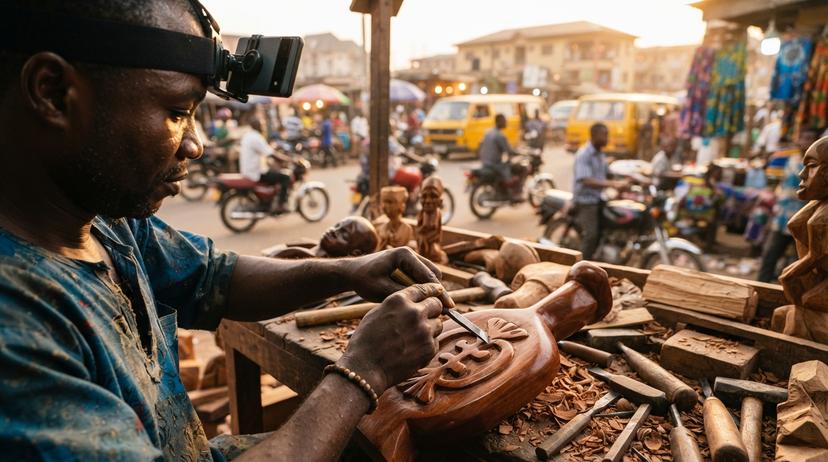
AI models learn from examples. For robots to perform tasks alongside humans, or for AI to understand human activity, they need to see and interpret actions. First-person video, like that captured by a worker wearing a head-mounted camera, offers a rich, natural view of task execution. This perspective is invaluable for understanding fine-grained manipulations, tool use, and interactions with objects. Without annotation, this video data is just a collection of images; with it, it becomes a powerful learning resource.
The goal is to teach AI systems to recognize patterns, predict outcomes, and even replicate human skills. For instance, a robot designed for manufacturing needs to learn not just to pick up a screw, but to do so with the correct grip, in the right orientation, and at the appropriate time within a larger assembly process. This level of understanding comes from detailed labels on the video data.

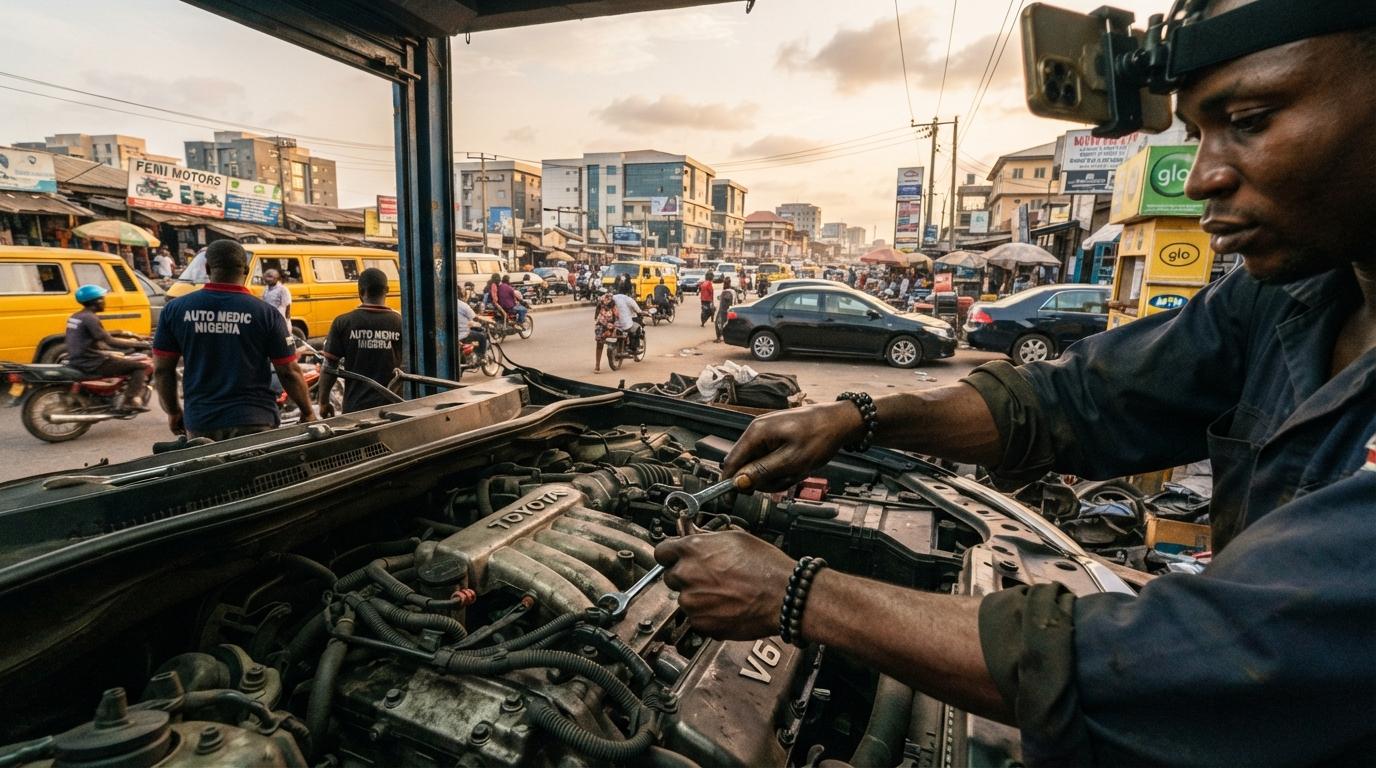
TrustAm focuses on collecting data from real-world Nigerian work environments, such as auto mechanics in Ladipo Market or phone repairers in Computer Village. This data is used to train AI for tasks that require understanding skilled manual labour. For more on why this type of data is sought after, see Why AI Labs Are Looking to Africa for Training Data in 2026.
What Are Hand Pose and Action Labels?
Annotation involves adding metadata to video frames. For first-person work video, two critical types of labels are hand pose and action recognition. Hand pose estimation identifies the precise position and orientation of a person's hands and fingers. This is vital for understanding how objects are grasped, manipulated, and interacted with. Action labeling, on the other hand, classifies the overall activity occurring in a video segment, such as 'tightening a bolt', 'sewing a seam', or 'mixing ingredients'.
Hand pose estimation can be as simple as identifying whether a hand is open or closed, or as complex as mapping out the coordinates of every finger joint. This detail is crucial for robots that need to mimic human dexterity. Action labels provide a higher-level understanding. For example, recognizing the action 'repairing a phone' can be further broken down by observing the hand poses involved in using a screwdriver or connecting a cable.
These labels are not just about what is happening, but also how it is happening. The nuances of human movement captured by hand pose data can differentiate between a skilled action and an unskilled one, providing AI with a deeper understanding of proficiency. This is a key difference from third-person video, as explained in Egocentric Video vs Third-Person Video: Which Does Your Robot Policy Need?
- Hand Pose Labels: Indicate the position, orientation, and shape of hands and fingers. This includes key points (joints) of the hand and fingers.
- Action Labels: Categorize the specific human activity being performed over a period of time. Examples include 'operating machinery', 'cooking', 'assembling parts'.
- Object Interaction: Often, labels will also specify which objects are being interacted with by the hands.
- Sequence Labels: For complex tasks, sequences of actions are labeled to show the order of operations.
The Annotation Process at TrustAm
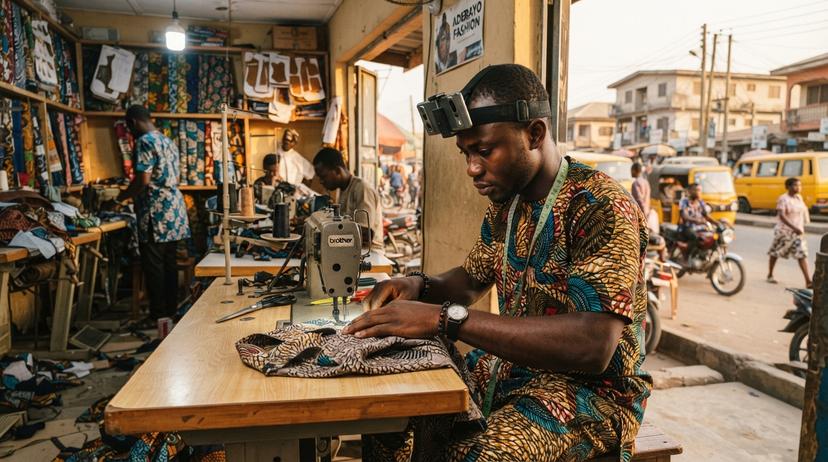
TrustAm’s data annotation process for first-person video is meticulous, ensuring the highest quality for AI training. It begins after the video recording is approved and passes initial quality checks. The video data, captured by contributors in trades like tailoring, auto mechanics, and cooking, is then passed to a team of trained human annotators.
These annotators use specialized software to draw bounding boxes around hands, segment them, and assign pose keypoints. For action labels, they review video segments to identify and classify the primary activity. The process requires a deep understanding of the work being performed to accurately label complex actions and subtle hand movements. For instance, distinguishing between 'cutting fabric' and 'hemming fabric' requires careful observation of the tools used and the motion patterns. This human oversight is critical, as AI models can only be as good as the data they are trained on. For more on quality assurance, see Dataset QA for Real-World Video: Approval Rates, Cut Reasons and Spot Checks.
Context is paramount. Annotators are trained to consider the environment and tools visible in the egocentric video to correctly interpret actions. If a mechanic’s hands are shown near an engine, the annotation should reflect actions related to that engine, such as 'tightening a bolt' or 'connecting a wire'. Bystander faces are automatically blurred to protect privacy, ensuring that only the relevant work actions and hand movements are the focus of the annotation.

The output of this process is structured data, often in formats like JSON, which can be easily ingested by machine learning models. This data can include timestamps, object IDs, hand pose coordinates, and action class labels. The reliability of this data is also a key consideration for buyers, who should always ask vendors detailed questions, as outlined in What to Ask an African Data Vendor Before You Buy AI Data.
Tools and Techniques for Annotation
Specialized annotation platforms are used to efficiently label video data. These tools provide interfaces for drawing boxes, marking keypoints, and assigning labels to video segments. For hand pose estimation, the software allows annotators to precisely click on the joints of the hand as they appear in each frame or across a series of frames. For action recognition, the annotator selects a start and end time for an action and assigns a predefined label from a taxonomy.
Some advanced techniques leverage AI to assist human annotators. For example, pre-trained models might suggest initial bounding boxes or pose estimations, which human reviewers then correct and refine. This semi-automated approach speeds up the annotation process while maintaining accuracy. The goal is to create comprehensive "datasheets" for datasets, as discussed in Datasheets for Datasets: How to Document AI Training Data From Nigeria.
Key features of effective annotation tools include:
- Intuitive User Interface: Easy to navigate for annotators.
- Frame-by-Frame and Interpolation Tools: Allows for precise annotation and efficient labeling across multiple frames.
- Customizable Label Sets: The ability to define specific actions and hand poses relevant to the data collection task.
- Quality Control Features: Mechanisms for reviewing and validating annotations, such as consensus mechanisms or automated checks.
- Export Options: Support for various data formats like JSON, XML, or COCO format, compatible with common ML frameworks.
These tools are essential for processing the large volumes of data required for robust AI model training. The choice of tools and techniques directly impacts the cost, speed, and quality of the final annotated dataset.
Applications of Annotated Egocentric Video Data
The detailed annotations generated from first-person work videos have a wide range of applications. In robotics, annotated data helps train robots to perform complex manipulation tasks, understand human intentions, and collaborate safely with people. For instance, models trained on data from Nigerian tailors can help robotic sewing machines achieve greater precision.
Beyond robotics, this data is crucial for developing advanced human-computer interaction systems, improving gesture recognition, and creating more intuitive user interfaces. It can also be used in AI safety research to better understand and predict human behaviour in critical situations. The data is particularly valuable for understanding skilled manual labour, a domain where detailed, first-person views are often the most informative. For a look at similar datasets, see the Ego4D dataset.
Specific applications include:
- Robotic manipulation: Training robots to grasp, hold, and manipulate objects with human-like dexterity.
- Activity recognition: Identifying and classifying human actions in real-world scenarios for surveillance, healthcare, or industrial monitoring.
- Human-robot collaboration: Enabling robots to understand human actions and intentions to work together effectively.
- Virtual and augmented reality: Creating more immersive and interactive experiences by accurately tracking user movements and interactions.
- Skill transfer: Developing AI systems that can learn and replicate complex manual skills from human demonstrations.
The National Artificial Intelligence Strategy in Nigeria highlights the importance of developing AI capabilities, and high-quality, locally sourced data like that collected and annotated by TrustAm is fundamental to achieving this goal. This data supports the development of AI solutions tailored to the Nigerian context, as outlined by the National Centre for Artificial Intelligence and Robotics (NCAIR).
Frequently Asked Questions
What is egocentric video?
How is hand pose estimated?
Why is contextual information important for action labeling?
Are bystander faces blurred in the data?
What happens to the annotated data after it's processed?
Need AI training data from Nigeria?
Egocentric video of skilled work and Nigerian-language speech, collected to order. Email [email protected] or request a free 10-hour sample; a person replies within one working day.
Founder and CEO of TrustAm. Building Nigeria's reputation marketplace for verified service providers. Reviews unlock only after real payments.
Disclosure: This article is published by TrustAm Data, part of TrustAm Limited. Links to /data pages are our own data service.
Sources & References
- Ego4D dataset— arxiv.org
- National Centre for Artificial Intelligence and Robotics (NCAIR)— ncair.nitda.gov.ng